Local AI

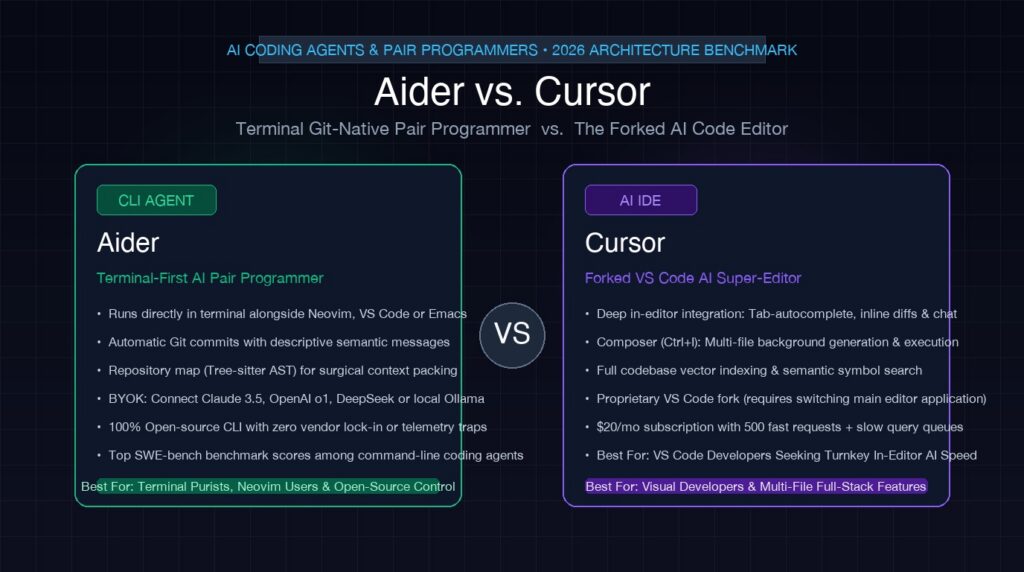
Aider vs Cursor comparison banner showing terminal pair programmer vs forked AI IDE

Aider vs. Cursor (2026): The Terminal Pair Programmer vs. Forked AI IDE Showdown

The developer ecosystem has reached a pivotal ideological fork in AI-assisted software engineering: should AI live inside your existing terminal...

Multi-agent autonomous graph network comparing LangGraph CrewAI and AutoGen

LangGraph vs. CrewAI vs. AutoGen (2026): The Multi-Agent Orchestration Benchmark

The software industry in 2026 has definitively moved past the era of single-prompt LLM wrappers. Production AI engineering now revolves...

High performance GPU server cluster running LLM inference with Ollama and vLLM

Ollama vs. vLLM (2026): High-Throughput Production Inference vs. Developer Ergonomics

Serving open-weight large language models in 2026 is no longer about whether you can run weights locally—it is an engineering...

vLLM vs Ollama throughput and continuous batching GPU benchmark

vLLM vs. Ollama (2026): The Ultimate Local LLM Throughput & Concurrency Benchmark

Every software engineer experimenting with open-weight models starts with Ollama. You install a single binary, execute ollama run llama3.3, and...

Developer terminal workstation debugging Ollama CUDA out of memory error with GPU VRAM telemetry

How to Fix Ollama Out of Memory (OOM) Errors: 5 Proven Fixes (2026)

Few errors halt local AI development faster than seeing Ollama crash with a cryptic CUDA error: out of memory, a...

Open-air GPU test bench running local LLM inference benchmarks with 24GB VRAM telemetry

Best GPU for Local LLMs Under $1,000 (2026): The 24GB VRAM Reality Check

If you have a strict $1,000 hardware budget to build or upgrade a dedicated local LLM workstation in 2026, you...
Apple Mac mini desktop developer workstation running local LLM inference telemetry

Mac mini M6 vs. M5 Pro for Local LLMs: How Much Unified Memory Do You Actually Need?

Sizing guide for Mac mini M6 and M5 Pro: what fits in 16GB, 24GB, 32GB, and 64GB unified memory, plus...
Developer workstation running local Qwen3-Coder-30B-A3B inference with GPU memory telemetry

Run Qwen3-Coder 30B-A3B Locally: 24GB VRAM Setup & Benchmarks

Can Qwen3-Coder-30B-A3B run on a 24GB GPU? Here is the estimated VRAM math, Ollama and vLLM commands, 256K context limits,...
vLLM vs. Ollama vs. SGLang in 2026: The Real-World Tokens/Second & VRAM Benchmark

vLLM vs. Ollama vs. SGLang in 2026: The Real-World Tokens/Second & VRAM Benchmark

Which local LLM engine truly maximizes your hardware? We benchmarked vLLM, Ollama, and SGLang on an RTX 4090 across single-stream...