Skip to content
SaaS
Glance
SaaS
Glance
Back-End as a Service
Local AI
AI Automation
Reviews
ERP System
Project Management
Search
Search
Connect with us
Facebook
Twitter
Youtube
Back-End as a Service
Local AI
AI Automation
Reviews
ERP System
Project Management
Back-End as a Service
Local AI
AI Automation
Reviews
ERP System
Project Management
Search
Search
Local AI
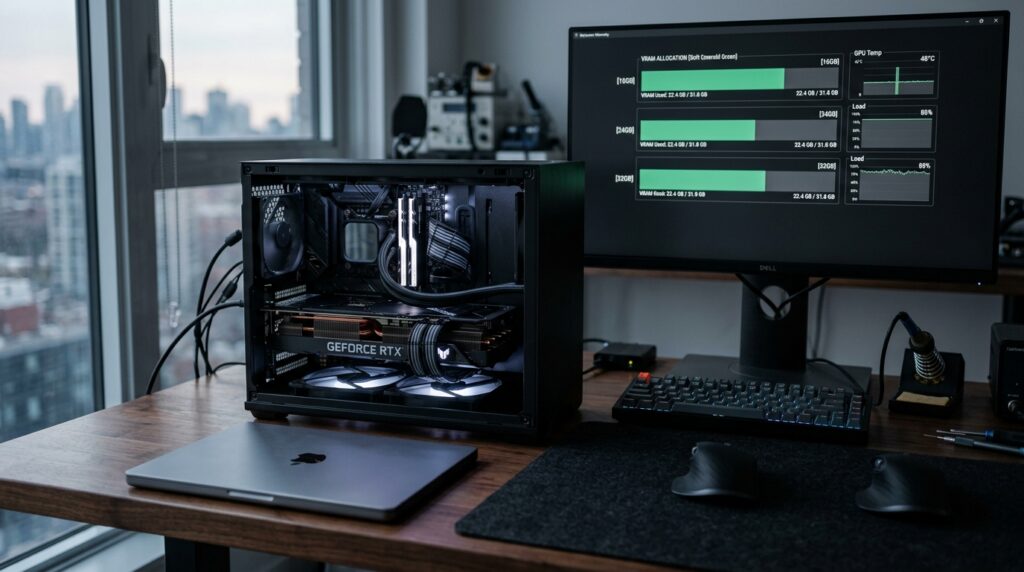
Which LLMs Can You Actually Run on 16GB, 24GB, and 32GB VRAM? The Realistic Hardware Guide
Stop guessing with VRAM. Practical 2026 hardware guide for running local LLMs on 16GB, 24GB, 32GB, and 48GB setups—GQA KV...
Brian Walsh
September 20, 2026
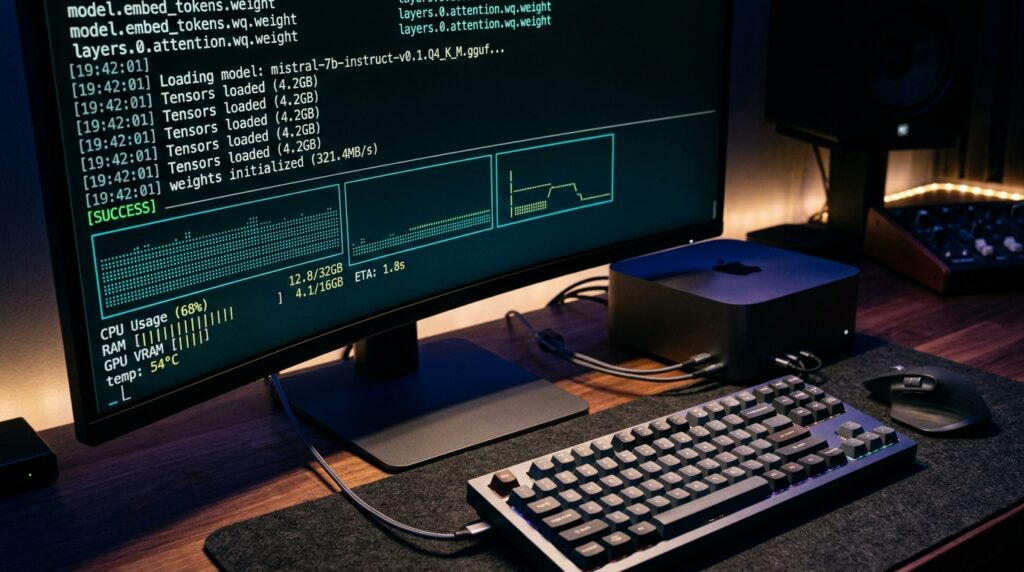
Can You Run DeepSeek-V4.1-Flash Locally? The 510GB Hardware Reality, vLLM & Ollama Cloud Explained
Can your hardware handle DeepSeek-V4.1-Flash? Here is the 510GB hardware reality check, why 8B active does not equal an 8B...
Brian Walsh
September 20, 2026
Previous
Page
1
Page
2
Next