AI Automation

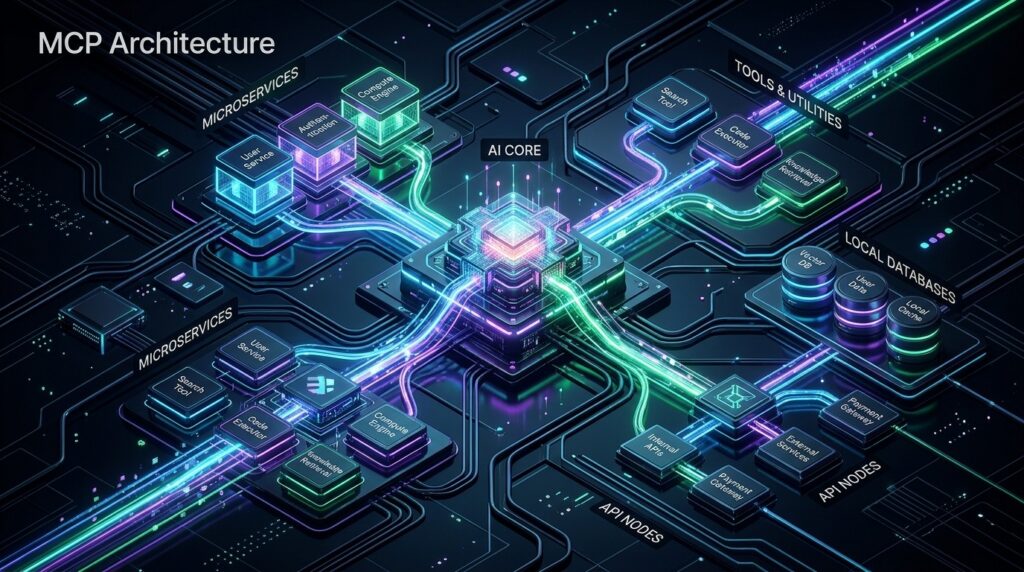
Multi-agent autonomous graph network comparing LangGraph CrewAI and AutoGen

LangGraph vs. CrewAI vs. AutoGen (2026): The Multi-Agent Orchestration Benchmark

The software industry in 2026 has definitively moved past the era of single-prompt LLM wrappers. Production AI engineering now revolves...

High performance GPU server cluster running LLM inference with Ollama and vLLM

Ollama vs. vLLM (2026): High-Throughput Production Inference vs. Developer Ergonomics

Serving open-weight large language models in 2026 is no longer about whether you can run weights locally—it is an engineering...

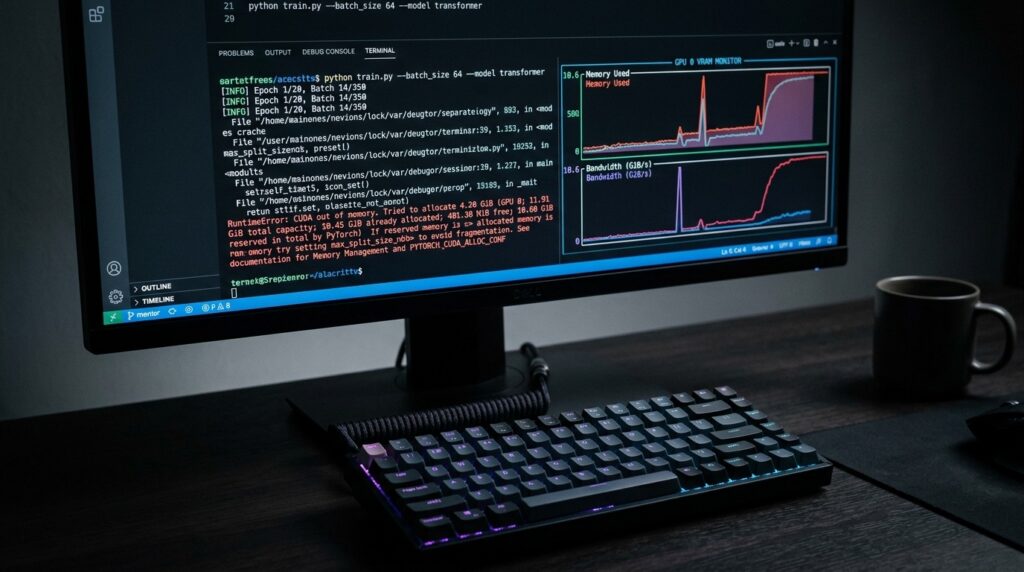
Developer terminal workstation debugging Ollama CUDA out of memory error with GPU VRAM telemetry

How to Fix Ollama Out of Memory (OOM) Errors: 5 Proven Fixes (2026)

Few errors halt local AI development faster than seeing Ollama crash with a cryptic CUDA error: out of memory, a...

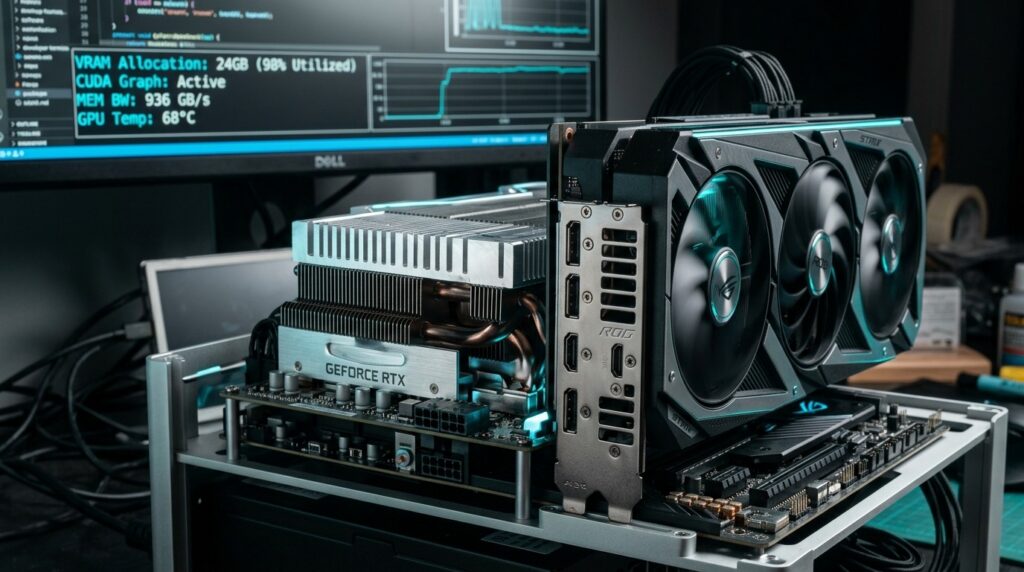
Open-air GPU test bench running local LLM inference benchmarks with 24GB VRAM telemetry

Best GPU for Local LLMs Under $1,000 (2026): The 24GB VRAM Reality Check

If you have a strict $1,000 hardware budget to build or upgrade a dedicated local LLM workstation in 2026, you...
Apple Mac mini desktop developer workstation running local LLM inference telemetry

Mac mini M6 vs. M5 Pro for Local LLMs: How Much Unified Memory Do You Actually Need?

Sizing guide for Mac mini M6 and M5 Pro: what fits in 16GB, 24GB, 32GB, and 64GB unified memory, plus...
Developer workstation running local Qwen3-Coder-30B-A3B inference with GPU memory telemetry

Run Qwen3-Coder 30B-A3B Locally: 24GB VRAM Setup & Benchmarks

Can Qwen3-Coder-30B-A3B run on a 24GB GPU? Here is the estimated VRAM math, Ollama and vLLM commands, 256K context limits,...
vLLM vs. Ollama vs. SGLang in 2026: The Real-World Tokens/Second & VRAM Benchmark

vLLM vs. Ollama vs. SGLang in 2026: The Real-World Tokens/Second & VRAM Benchmark

Which local LLM engine truly maximizes your hardware? We benchmarked vLLM, Ollama, and SGLang on an RTX 4090 across single-stream...
Developer workstation displaying GPU memory monitoring and local LLM VRAM utilization

Which LLMs Can You Actually Run on 16GB, 24GB, and 32GB VRAM? The Realistic Hardware Guide

Stop guessing with VRAM. Practical 2026 hardware guide for running local LLMs on 16GB, 24GB, 32GB, and 48GB setups—GQA KV...
How to Run DeepSeek-V4.1-Flash Locally: Hardware Requirements, Ollama Setup, and Benchmarks

Can You Run DeepSeek-V4.1-Flash Locally? The 510GB Hardware Reality, vLLM & Ollama Cloud Explained

Can your hardware handle DeepSeek-V4.1-Flash? Here is the 510GB hardware reality check, why 8B active does not equal an 8B...