Discover what powers modern business

From AI automation to enterprise systems, explore in-depth guides and reviews.

Fresh Insights & Analysis

Stay updated with our newest articles, reviews, and industry deep-dives.
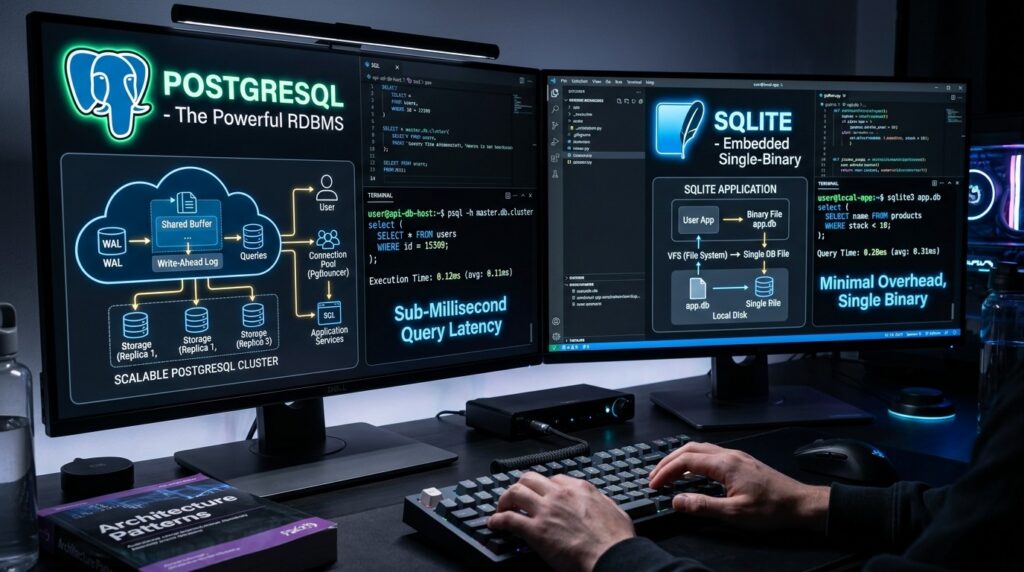
PocketBase vs Supabase open source self-hosted backend architecture comparison
Back-End as a Service

PocketBase vs. Supabase (2026): Which Open-Source Backend Should You Self-Host?

The developer pushback against cloud vendor lock-in and unpredictable serverless billing has reached a tipping point in 2026. For engineers

Melissa Bennett
Cursor vs Windsurf modern AI developer code editor comparison
Reviews

Cursor vs. Windsurf (2026): Which AI IDE Actually Writes Better Code?

The developer landscape in 2026 has fundamentally shifted from autocompletion to agentic orchestration. The two undisputed titans dominating developer workstations

Robert Sullivan
Developer terminal workstation debugging Ollama CUDA out of memory error with GPU VRAM telemetry
Local AI, AI Automation

How to Fix Ollama Out of Memory (OOM) Errors: 5 Proven Fixes (2026)

Few errors halt local AI development faster than seeing Ollama crash with a cryptic CUDA error: out of memory, a

Brian Walsh
Open-air GPU test bench running local LLM inference benchmarks with 24GB VRAM telemetry
Local AI, AI Automation

Best GPU for Local LLMs Under $1,000 (2026): The 24GB VRAM Reality Check

If you have a strict $1,000 hardware budget to build or upgrade a dedicated local LLM workstation in 2026, you

Brian Walsh
Apple Mac mini desktop developer workstation running local LLM inference telemetry
Local AI, AI Automation

Mac mini M6 vs. M5 Pro for Local LLMs: How Much Unified Memory Do You Actually Need?

Sizing guide for Mac mini M6 and M5 Pro: what fits in 16GB, 24GB, 32GB, and 64GB unified memory, plus
Brian Walsh
Developer workstation running local Qwen3-Coder-30B-A3B inference with GPU memory telemetry
Local AI, AI Automation

Run Qwen3-Coder 30B-A3B Locally: 24GB VRAM Setup & Benchmarks

Can Qwen3-Coder-30B-A3B run on a 24GB GPU? Here is the estimated VRAM math, Ollama and vLLM commands, 256K context limits,
Brian Walsh

Stay ahead in SaaS

Get weekly insights on AI automation, backend tools, ERP systems, and more — delivered straight to your inbox.

No spam. Unsubscribe anytime.